HomeServerBlog high availability tool
Split-Brain Risk Calculator
Estimate quorum safety, tolerated failures, split-brain probability, and the fencing window for Proxmox, Ceph, Pacemaker, Patroni, Keepalived, and home HA lab clusters.
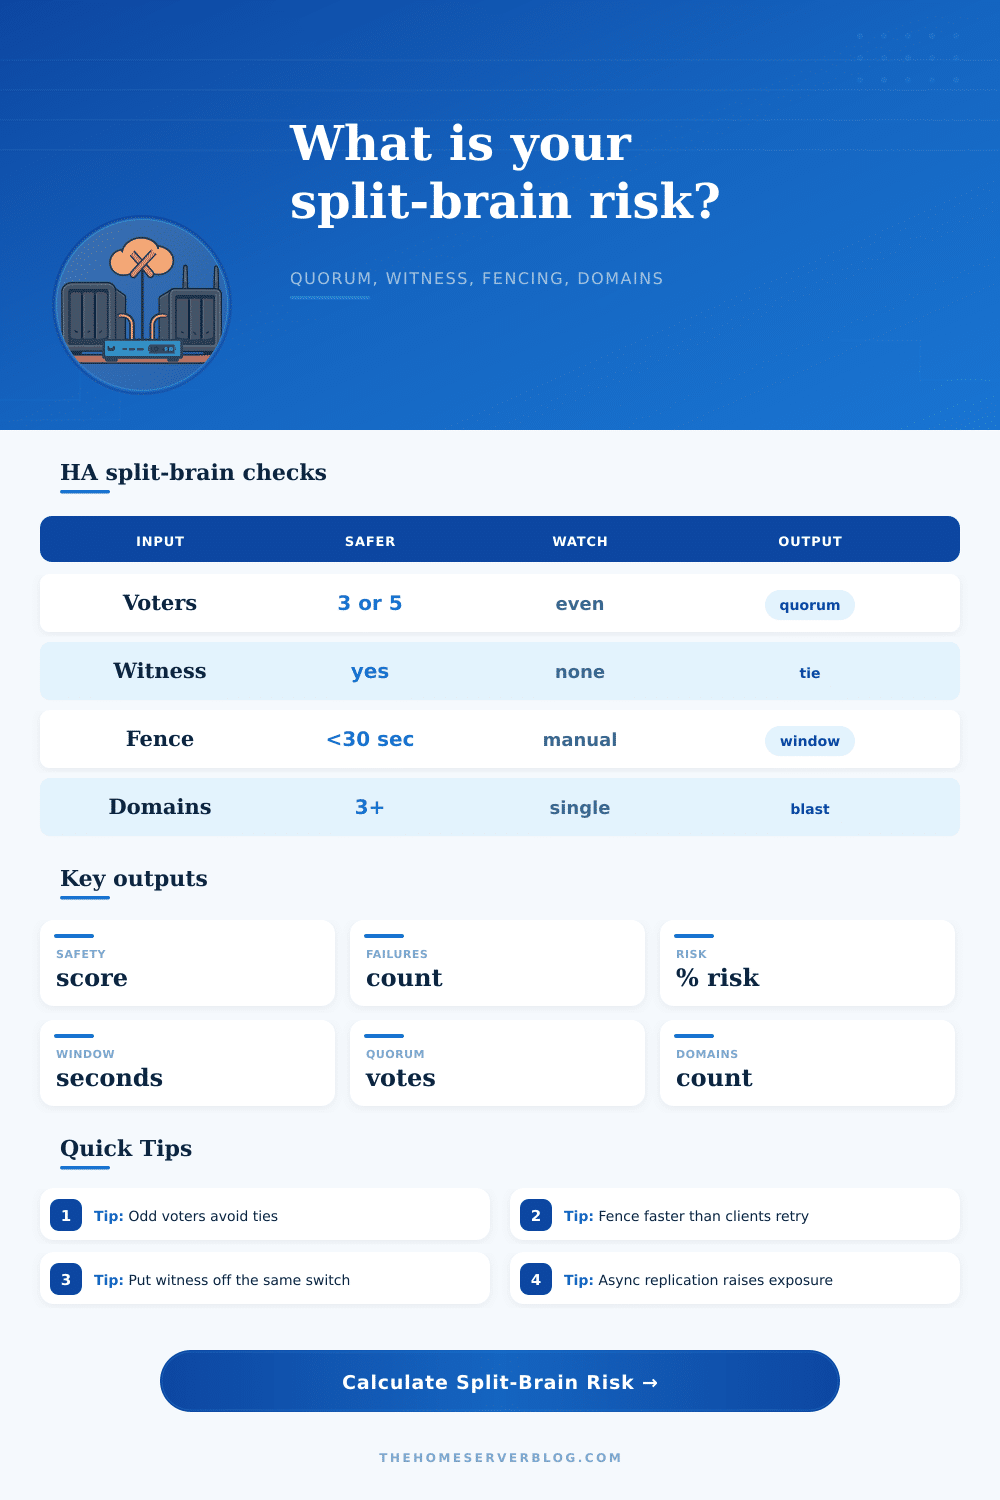
Majority, witness, and failure domain score.
Votes that can disappear while still keeping quorum.
Partition probability adjusted by quorum and fencing controls.
Interval where both sides may still believe they are alive.
Calculation breakdown
Majority vote needed to continue serving writes.
Votes that can be lost before the cluster must stop.
Heartbeat detection plus external or self-fencing delay.
Suggested attention level from the combined score.
2-node pair
FragileWithout a witness, a clean partition has no neutral majority and often depends on priority, manual action, or storage locks.
3 voters
1 failureA classic home lab shape: two of three votes continue, one isolated member loses quorum.
5 voters
2 failuresFive voters tolerate more loss, but only when domains and links do not fail in the same blast radius.
Fast fencing
<30 secShort fencing windows reduce the chance of two sides accepting writes during delayed membership repair.
| Voter layout | Quorum needed | Tolerated vote loss | Split-brain note |
|---|---|---|---|
| 2 nodes, no witness | 2 of 2 or manual | 0 | Even split has no independent majority; use a witness, lease, or hard fencing. |
| 2 nodes plus qdevice | 2 of 3 | 1 | Witness breaks the tie if it is not on the same power and switch path. |
| 3 voting nodes | 2 of 3 | 1 | Simple majority works well for Proxmox, Patroni, and many DCS-backed stacks. |
| 5 voting nodes | 3 of 5 | 2 | Better fault cushion, but latency and domain spread still matter. |
| Fencing path | Typical delay | Reliability | Planning implication |
|---|---|---|---|
| Manual operator action | Minutes | Low | Useful for labs, risky for unattended write services. |
| IPMI or PDU STONITH | 10 to 45 sec | High | Strong for Pacemaker and storage services if power control is tested. |
| Watchdog self-fence | 5 to 20 sec | High | Good local stop signal when membership or lease renewal fails. |
| Lease denial through DCS | 5 to 30 sec | Medium high | Works when the DCS itself has healthy quorum and strict TTLs. |
| Replication mode | Write behavior | Divergence risk | Best fit |
|---|---|---|---|
| Asynchronous | Primary can acknowledge before peers persist | High | Backups, replicas, read-mostly services, WAN replicas. |
| Semi-synchronous | Some peer confirmation before commit | Medium | Databases that need lower data-loss risk with tolerable latency. |
| Synchronous quorum | Majority or quorum confirms the write | Low | Ceph, raft-like control planes, strongly consistent stores. |
| Shared storage | Multiple heads guard one data copy | Medium | Requires lock managers and fencing to prevent dual writers. |
| Failure domain layout | Good signal | Weak signal | What to change |
|---|---|---|---|
| Single rack or shelf | Simple cabling | Shared power and switch loss | Separate power paths and at least one witness elsewhere. |
| Two rooms or racks | Better maintenance isolation | Even site split risk | Add a third voter, qdevice, or remote arbitrator. |
| Three domains | Natural majority placement | Latency if stretched too far | Keep quorum traffic stable and monitor heartbeat jitter. |
| Stretched sites | Survives local faults | WAN partitions become membership events | Use a third-site witness and explicit site priority policy. |
| HA quorum/fencing comparison | Quorum control | Fencing control | Risk posture |
|---|---|---|---|
| Proxmox with corosync | Odd votes or qdevice | Watchdog, HA manager, external power | Good when corosync links and qdevice are separated. |
| Ceph monitor quorum | Monitor majority | OSD down/out plus client behavior | Strong consistency, but small clusters dislike two-way splits. |
| Patroni PostgreSQL | DCS majority and leader lock | TTL expiry, callbacks, optional watchdog | Safe when old primary cannot write after lease loss. |
| Pacemaker cluster | Corosync votequorum | STONITH first-class requirement | Strongest when every node has tested fencing. |
| Keepalived VRRP pair | Priority election | Usually none | Fine for VIP failover, weaker for stateful writers. |
Crashing the whole thing? That’s easy to fix. But what about worst-case scenario for an always-on infrastructure. When the system doesn’t crash, but something just isn’t right? Maybe you have a network partition that splits your cluster in half, with each half running normaly. Except neither knows they’re wrong because the other half is dead silent. Welcome to split-brain syndrome: where data consistency becomes guesswork. Who wins? Duplicated records. Who loses? Corruption.
Plug your fencing parameters and your node count into calculator above, and it will do the math for you. No need to trace quorum logic yourself across all failure combinations.
How to Fix Split-Brain Problems
In distributed systems, quorum is the tie-breaker. Without an odd number of entities making the decision, you cannot reach a majority without ending in a deadlock. In a three-node system, if one node go down, there are still enough nodes to keep it going. But with just a couple of nodes without some kind of arbitrator outside the system, then you’re up against a simple question: when the network splits, what do you do?
The score says how safe you are depending on how many votes you have plus whether you add quorum or witness devices that can breaks the tie. A single vote from somewhere else can turn a creaky two-node connection into something really strong that can survive if one end go offline. And people screw that up by thinking “more servers” equals “resilient.” It doesn’t. It’s about having more paths to votes.
Adding to all that, fencing also establishes a time-to-stasis: the amount of time it takes for an isolated node to shut down write acceptance. The calculator finds your “fencing window” by adding up actual power-off/lease-denial delays and heartbeat timeouts. A large enough fence exposes you to the possibility that each side of the split will commit conflicting transactions without realizing they’ve lost their quorum. Fast fencing narrows that exposure, but does so only if there’s a reliable way (such as a watchdog timer or IPMI) to force things out-of-band if necessary, and those methods actualy work in testing. Manual intervention adds human delay, widening your window for divergence in unattended hours.
After a split, you are faced with the decision of what risk level you can tolerate given which replication mode was selected. If you picked synchronous replication, writes don’t commit without quorum acknowledgement and strong consistency is guaranteed. However, the system will be more obviously crippled in the face of network flakiness. On the other hand, asynchronous replication allows services to continue humming along over great distances at the expense of possible data loss upon sudden primary failure. The calculator reflects this compromise, understanding that underneath an eventual consistent appearance lies some hidden brittleness waiting to be exposed when the next recovery scenario demands a conflict resolution. No architecture does perfect uptime AND perfect accuracy; it’s up to you to determine what best suits your workload.
The abstraction called vote translates into failure domains in the real world. Don’t put your nodes on the same power circuit, rack, or availability zone. You might think you have redundancy, but if they’re all on one power supply then you only have one failure domain and a single switch going down could take down several voter at once. That’s clear from page’s reference tables. They explain why, for example, data center-stretched clusters need third-site witness nodes to break a deadlock between two data centers that each hold half of the votes. This often matters more than your software configurations do, because geography tends to determine what makes for a viable quorum.
Running through some of those scenarios exposes flaws that planning misses entirely. Your theoretical perfect layout may have a flawed fencing mechanism when under load. Routine maintenance can cause network jitter and result in false positives. Running it all through the calculator gives you a baseline score, but validating in a lab environment by deliberately knocking out nodes is how you know if the losing side will actually stop serving traffic in the configured window. If not, then your quorum configuration is nothing more than hoping for the best until something happens in production.
In short, dealing with split-brain risk means giving up on perfection and embracing good enough. Because there’s a non-zero chance of partitioning occurring at any moment, what matters changes from “make sure this doesn’t happen” to “how do I make sure it fails safely, then recovers quickly?” And we leave it to the calculator above to work out the maths for you. What does it tell you? Is your existing configuration too close to the edge (fragile!) or does it have enough padding to survive normal infrastructure changes? Keep in mind that these calculations rely on your components being honest; if your power supplies aren’t independent, no amount of voting logic would of prevent the ensuing clusterfuck.