HomeServerBlog reliability and redundancy planner
Parallel System Reliability Calculator
Estimate k-out-of-n reliability for parallel routers, UPS modules, cluster nodes, fans, power supplies, controllers, storage paths, or standby appliances using unit reliability, mission time, failure rate, load sharing, common-cause beta, repairability, and confidence margin.
1Parallel system presets
2Reliability, mission, and redundancy inputs
Calculation breakdown
Reliability posture
3Live reliability, failure, downtime, and reserve summary
Time, load, standby, and confidence adjusted.
Derived from the adjusted hourly failure rate.
Useful for reserve headroom checks.
How many units can be lost before failure.
4Redundancy architecture grid
5Parallel reliability tables
Required-unit sensitivity
| Required units | Reserve | Reliability | Failure risk |
|---|
Installed-unit sensitivity
| Installed units | Need | Reliability | Downtime |
|---|
Mission-time curve
| Mission hours | Unit reliability | System reliability | Failure risk |
|---|
Common-cause beta curve
| Beta | Independent gain | Reliability | Lost to beta |
|---|
6Reference tables
Standby and load exposure factors
| Mode | Wear factor | Switch penalty | Typical use |
|---|---|---|---|
| Active-active | 1.00 x load factor | Very low | Routers, clustered services, parallel links |
| Hot standby | 0.85 x load factor | Low | Firewall HA, controllers, warm power paths |
| Warm standby | 0.45 x load factor | Medium | Booted spare, replicated service, staged node |
| Cold standby | 0.15 x load factor | Higher | Shelf spare, backup router, powered-off node |
Common-cause beta guide
| Beta range | Meaning | Examples | Mitigation |
|---|---|---|---|
| 0-1% | Very independent | Different rooms, separate firmware trains | Keep isolation documented |
| 1-3% | Typical HA lab | Shared rack, dual power, similar config | Separate power and test failover |
| 3-8% | Shared dependency | Same PDU, same switch, same update batch | Stagger maintenance and diversify paths |
| 8%+ | Redundancy capped | One room, one cooling path, one operator action | Fix common causes before adding units |
7Reliability planning tips
This calculator will show you how parallel systems can fail in tandem (known as the parallel system reliability calculator). Most of the time when your system goes down it’s not due to a flaw in hardware; it’s just a dumb thing that happens (usualy late at night), which is why building redundancy make sense. You know you trust the math, but you often ignore shared risks.
This calculator tell you whether one router or two is more resilient. Or it’ll tell you why they both might fall over. This is K-out-of-n reliability. You’ve got n units total. How many do you need to be working in order to sustain your service? K out of n. One of two router? Two of three? Quorum on a storage cluster? It’s up to you. The tool does the binomial math for you.
Why Adding More Parts Does Not Always Help
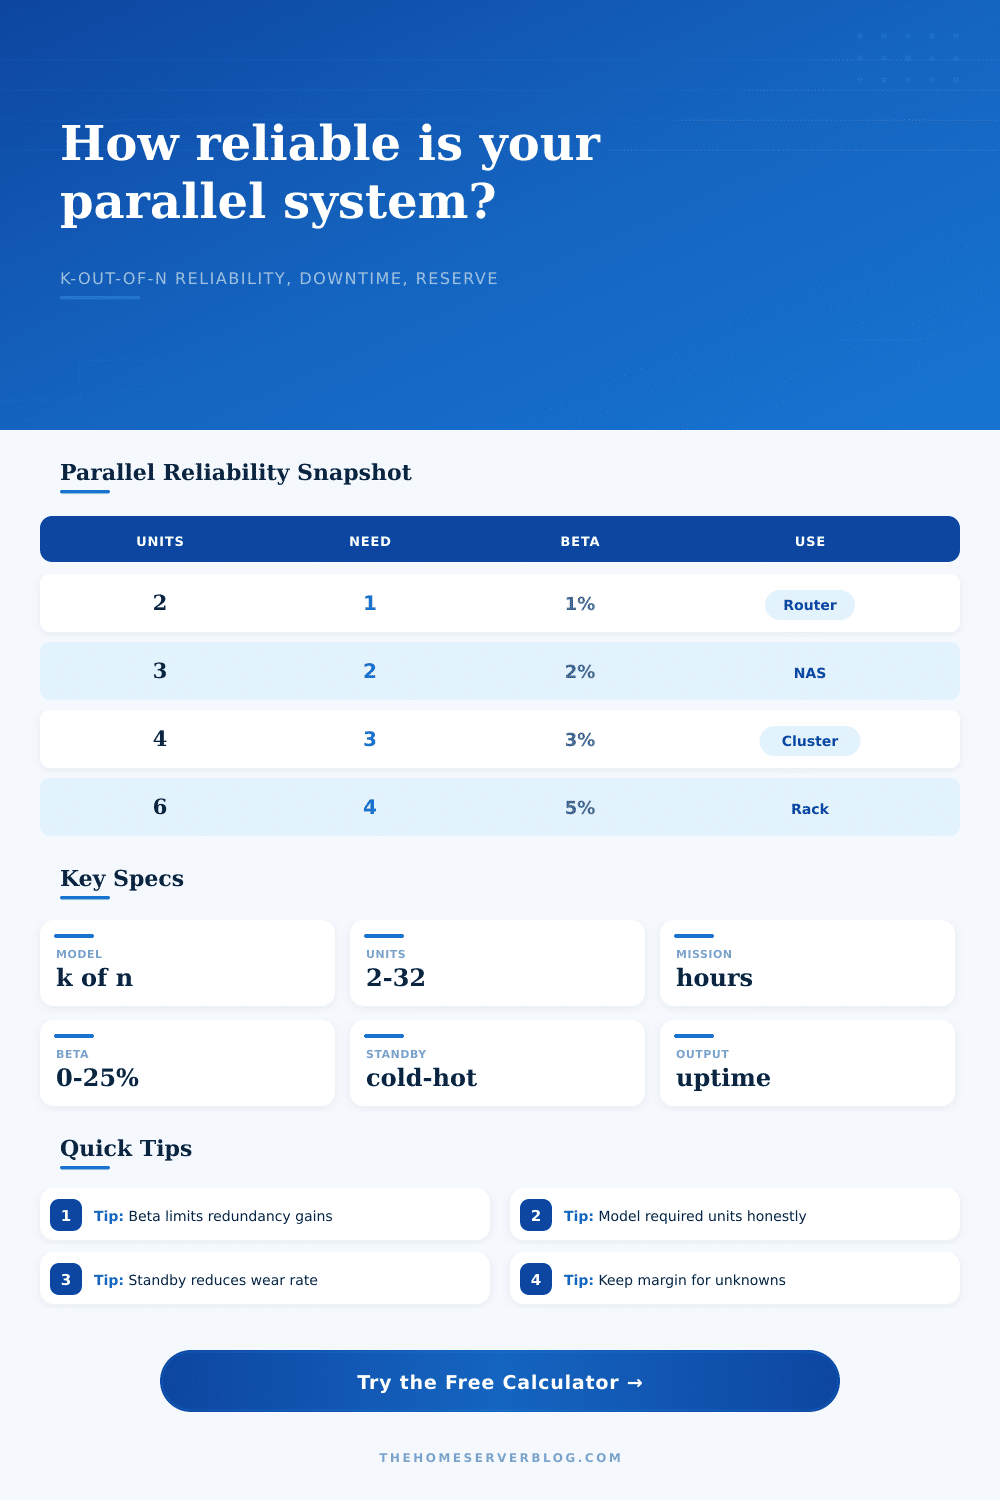
Most folks think that if they add more spares, their uptime will go up linearally. They are usually wrong. When you start accounting for common-cause failure, diminishing returns kicks in very quickly. That’s the biggest input: the beta factor. What is the beta? Beta is the percent of failures that will strike every unit simultaneousy. A common cooling fan can overheat entire rack. Identical firmware bug. A shared power circuit. Add a third node and it add almost nothing to a high-beta situation.
That’s evident in the calculator above. It takes away any sense of security that comes with physically duplicating something without logically separating it. Five server doesn’t mean anything if they’re all plugged into same PDU.
Reliability depends based off standby mode. What about standby? Is it cold or hot or warm? What happens during the switchover? Hot/warm standby has a switchover penalty. The tool will adjust the wear rate based on whether your standby is hot, warm, cold, or active. If you have more than one doing the job, do they share the load? (active-active) That changes failure dynamics. If you’re running fans out of a wall and you lose one, now the others has to work harder. The inputs capture changes in the stress and the load-sharing factor.
Reliability is also dependent on mission time. Over time, reliability degrades. What’s 99.9 percent reliable for a week will be 95 percent after a year. The calculator allow you to account for degradation over different mission times. As you accumulate hours, you can watch your uptime guarantee degrade. It provides a way for you to schedule maintenance in advance of hitting the moment where the numbers work against you. No more guesses about which part needs replacing; now you know and when.
There’s even a bunch of reference tables on the page that let you sanity check your assumptions. It presents standby wear factors and typical beta ranges. It doesn’t require you to pull numbers out of your ass. See where the quorum requirement moves the reliability curve if you’re doing a Proxmox cluster. That’s very different than just an N+1 power supply shelf. Quorum systems has different failure modes than load-balanced pairs.
Risk management means reliability engineering when I use that term. Managing risk is not the same as removing all risk. There’s no purchase order item that protects you from an outage. What you can do is design systems to fail safely and recover consistently. This requires you to make honest inputs to the tool. Confess that your spares are on the same power source. Confess that your firmware is the same. Your numbers will reflect this. They’ll look worse. But your design will be stronger.
So begin simply and try out your failover process. Expand only if it makes mathematical sense. Remember that redundancy is not free, of both money and headache. Every spare should of enhance resilience. That’s how you know you have a resilient system versus a hobby set up. You don’t trust luck anymore. You trust the moddern model.